Why Human Values Matter in AI
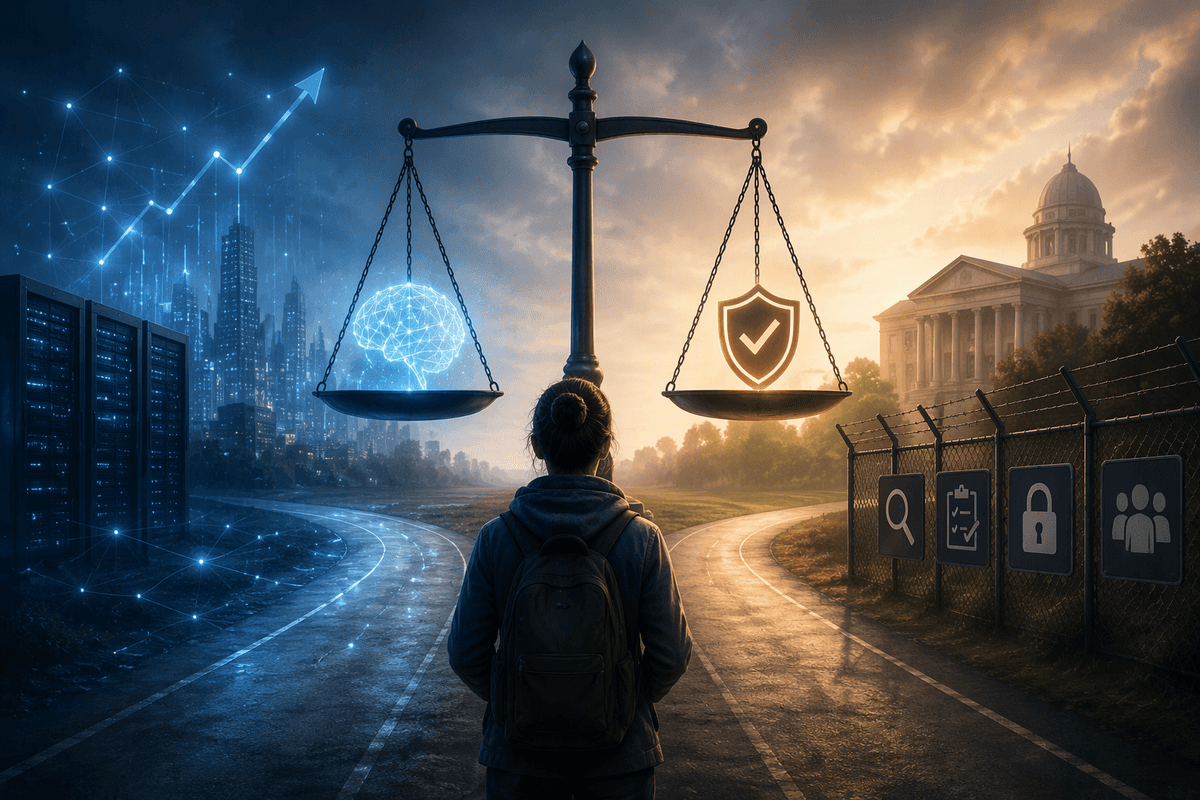
When an AI system approves a loan, recommends medical care, filters job applications, or decides what information people see, it does more than calculate. Its choices can affect opportunities, safety, privacy, and dignity. That is why accuracy alone is not enough. A system may follow its instructions precisely and still produce outcomes people consider unfair or harmful.
Human values matter because AI operates in situations where rules are incomplete and reasonable people may disagree. Fairness, honesty, autonomy, and minimizing harm can point in different directions, especially when data reflects existing social inequalities. Alignment therefore means more than obeying commands. It means designing and evaluating systems so their behavior remains understandable, accountable, and responsive to human judgment. No single group can settle every value question, and even well-designed systems can behave unpredictably in unfamiliar circumstances.
Which Values Should an AI System Follow?
Imagine an AI hiring tool choosing between two qualified applicants. Should it treat everyone identically, correct for patterns of past discrimination, protect personal privacy, or prioritize the candidate most likely to succeed? Each choice reflects a value, and no single list can resolve every case. Still, some principles provide a useful starting point: respect for human autonomy, fairness, honesty about uncertainty, privacy, safety, and accountability when something goes wrong.
These values should not be treated as simple commands. “Be fair,” for example, does not explain whether fairness means equal treatment, equal opportunity, or reducing unequal outcomes. A system may also need to balance privacy against public safety or individual choice against preventing serious harm. The practical goal is not to make AI perfectly neutral, because neutrality is often impossible. It is to make the values behind important decisions explicit, justify how they are balanced, and create ways for affected people to question or appeal the result. That requires public input and ongoing review, since values can vary across communities and circumstances.
Turning Abstract Values Into System Behavior
A value becomes meaningful only when it changes what a system does in a specific situation. If developers say an AI should respect privacy, they must decide which data it may collect, how long it can retain it, and when a person can refuse its use. If fairness is a goal, they need to examine training data, compare error rates across groups, and determine whether people can challenge decisions. These choices turn broad principles into design requirements, testing procedures, and operating rules.
That translation is difficult because systems often learn patterns rather than principles. An AI may be instructed to treat applicants equally but rely on historical data that reflects unequal access to education or employment. It may produce polite, confident explanations without actually revealing why it made a decision. Guardrails can reduce these problems, but they cannot anticipate every context, and stricter controls may also limit usefulness or delay legitimate decisions. Trust therefore depends on more than a written policy: people need evidence that the system behaves consistently, exposes important limitations, and allows meaningful human review when its judgment is uncertain or harmful.
Who Gets to Define the Right Values?
Consider an AI system used to decide who receives public benefits. Government officials may define success as consistent enforcement, while applicants may value flexibility when paperwork fails to capture their circumstances. Disability advocates, community groups, engineers, and auditors may identify risks that the organization commissioning the system overlooked. The question is not only which values sound reasonable, but whose experiences shape the decisions and whose interests carry the most weight.
Leaving these choices to developers or company executives can make alignment reflect a narrow set of assumptions, even when the system appears neutral. Broad public participation is important, but it is not simple: large surveys may favor easily stated opinions, while affected groups may lack time, access, or influence. Some decisions also involve rights and safety that should not be left to majority preference alone. A credible process therefore combines democratic input with domain expertise, legal protections, independent review, and direct involvement from people who bear the consequences. Even then, agreement may remain impossible. Alignment is more trustworthy when disagreements are visible, reasons are documented, and institutions can revise the system rather than presenting one group’s judgment as universal.
When Values Conflict in Real Decisions
A self-driving car facing an unavoidable crash may need to protect its passengers, reduce harm to pedestrians, and follow traffic rules, even when those goals cannot all be satisfied. Similar conflicts arise when a health system recommends scarce treatment, a content platform removes harmful material, or a fraud detector blocks an unusual transaction. The problem is not simply choosing the “right” rule. It is deciding which value should take priority, under what conditions, and with whose authority.
AI systems handle these conflicts through priorities set in data, software, policies, and human oversight. Those priorities can produce unfair results even when each individual rule seems reasonable. Protecting privacy may reduce the information needed to detect danger; allowing user choice may expose vulnerable people to manipulation; avoiding false accusations may let some harmful activity continue. There is also a practical cost to demanding human review in every difficult case: decisions may become slower, more expensive, or inconsistent. Alignment therefore requires more than listing values. It requires making trade-offs explicit, testing who bears the risks, and providing appeals when an automated decision causes serious harm.
How Can We Tell If AI Is Aligned?
Suppose an AI loan system performs well in testing but rejects applications from one neighborhood far more often than others. Accuracy alone would not show whether it is aligned. Evaluators need to examine outcomes across affected groups, test how the system responds to unusual cases, and compare its decisions with the values it is supposed to uphold. They should also check whether explanations are accurate, whether uncertainty is disclosed, and whether people can correct bad information or appeal a decision.
Alignment cannot be established by a single benchmark or a company’s promise. Systems change when their data, users, or surroundings change, so monitoring must continue after deployment. Independent audits, real-world incident reports, user feedback, and records of overridden decisions can reveal problems that laboratory tests miss. The fairness measures may conflict, some harms are difficult to quantify, and access to the system’s data may be restricted. A reasonable judgment therefore asks not whether an AI is perfectly aligned, but whether its behavior is understandable, its risks are actively measured, and accountable people can intervene when it fails.
Alignment Is an Ongoing Human Responsibility
An AI system may perform responsibly today and create problems tomorrow as its data, users, or operating environment change. New uses can expose risks that were not visible during testing, while updates may alter how decisions are made. Human responsibility therefore continues after deployment. Organizations must monitor outcomes, investigate complaints, explain important changes, and give qualified people the authority to pause or replace a system when its effects become unacceptable.
This does not mean humans can guarantee perfect alignment. It means they remain responsible for setting limits, reviewing trade-offs, and deciding when efficiency is not worth the risk. Claims that an AI is “aligned” should be judged by evidence: transparent goals, meaningful evaluation, independent scrutiny, and realistic ways to correct harm. Trust is earned not by removing human judgment, but by using it openly and consistently over time.