Why “slowdown” keeps coming up in AI research
You’ve probably seen “slow down AI” used to mean everything from a short pause on the biggest training runs to broad regulation of products and deployments. It keeps resurfacing because modern AI progress is unusually tied to scale: bigger models, more compute, and larger datasets can produce visible jumps, sometimes faster than institutions can evaluate risks or set norms. That creates a recurring tension between “move fast” incentives (funding, benchmarks, product cycles) and “measure twice” needs (security testing, misuse analysis, reliability checks).
Slowdown talk also returns whenever a new capability surprises people, or when access concentrates in a few well-funded labs. If only a handful of groups can afford frontier experiments, researchers worry about safety corners being cut, uneven oversight, and a widening gap between what’s publishable and what’s actually happening behind closed doors. Even proponents admit a practical constraint: any slowdown worth noticing is expensive to monitor, and hard to align across countries and companies.
What counts as a slowdown, and who decides
Picture a lab planning its next model: “slowdown” could mean the run is delayed for an external review, resized to fit a compute threshold, or denied because the lab can’t access enough GPUs. Those are very different experiences. Some proposals target a narrow slice of work (only training above a certain compute budget, or only releasing weights), while others act indirectly through procurement rules, export controls, grant conditions, or liability standards for deployed systems. A product team may feel a slowdown as longer red-teaming and documentation cycles even if research continues at full speed.
Who decides also varies. Governments can set licensing, reporting, or compute monitoring requirements; funders and universities can condition money and cluster access; cloud providers and chip makers can enforce terms through capacity and contracts; and journals and conferences can shift norms around disclosure. If capability work moves to private, less-published channels, the field can “look” slower while risks and competition remain.
Which research slows: capabilities, safety, or both
In practice, most slowdown proposals aim first at capability-advancing work: frontier-scale pretraining, large fine-tunes that meaningfully raise performance, and releases that let others replicate those gains quickly. That focus is partly pragmatic—big training runs are easier to define, count, and gate than everyday research—but it also means “slowdown” can land unevenly. A lab might still publish new prompting methods, evaluation datasets, or efficiency tricks, even if it can’t run the next massive experiment. And some efficiency work is a double-edged sword: it can look like “making do with less” while actually lowering the cost of building strong systems.
Safety research doesn’t automatically speed up under a slowdown. If access to frontier models and logs is restricted, external researchers may lose the very artifacts they need to test for misuse, emergent behavior, or jailbreaks. Conversely, internal safety teams can get more time for audits, incident drills, and red-teaming, but that time is expensive and often competes with product deadlines. The result is less “capabilities versus safety” than a reallocation of who gets to do which kind of work, and with what tools.
Practical mechanics: compute caps, access, and data
A slowdown becomes real when it changes what you can book, buy, or download. A compute cap can be explicit (a licensing threshold above a training run size) or practical (a university cluster that won’t schedule jobs over a limit, or a cloud contract that requires extra approvals). Even “soft” caps—higher reporting burdens, mandatory evaluations, or longer security sign-offs—function like a throttle because they add calendar time and coordination overhead. The friction tends to hit small labs first: they have fewer alternative clusters, less bargaining power with providers, and less staff time for compliance.
Access is the second lever. If frontier weights are restricted, researchers shift toward API-based work, where rate limits, logging, and usage policies shape what experiments are feasible. That can help monitoring, but it also makes certain studies hard to reproduce and can quietly narrow research questions to whatever the interface exposes.
Data is the third bottleneck. Limits on scraping, provenance requirements, or bans on certain sources push teams toward curated datasets and licensing deals, which raises costs and can reduce coverage of niche languages and domains.
The hidden second-order effects on labs and careers
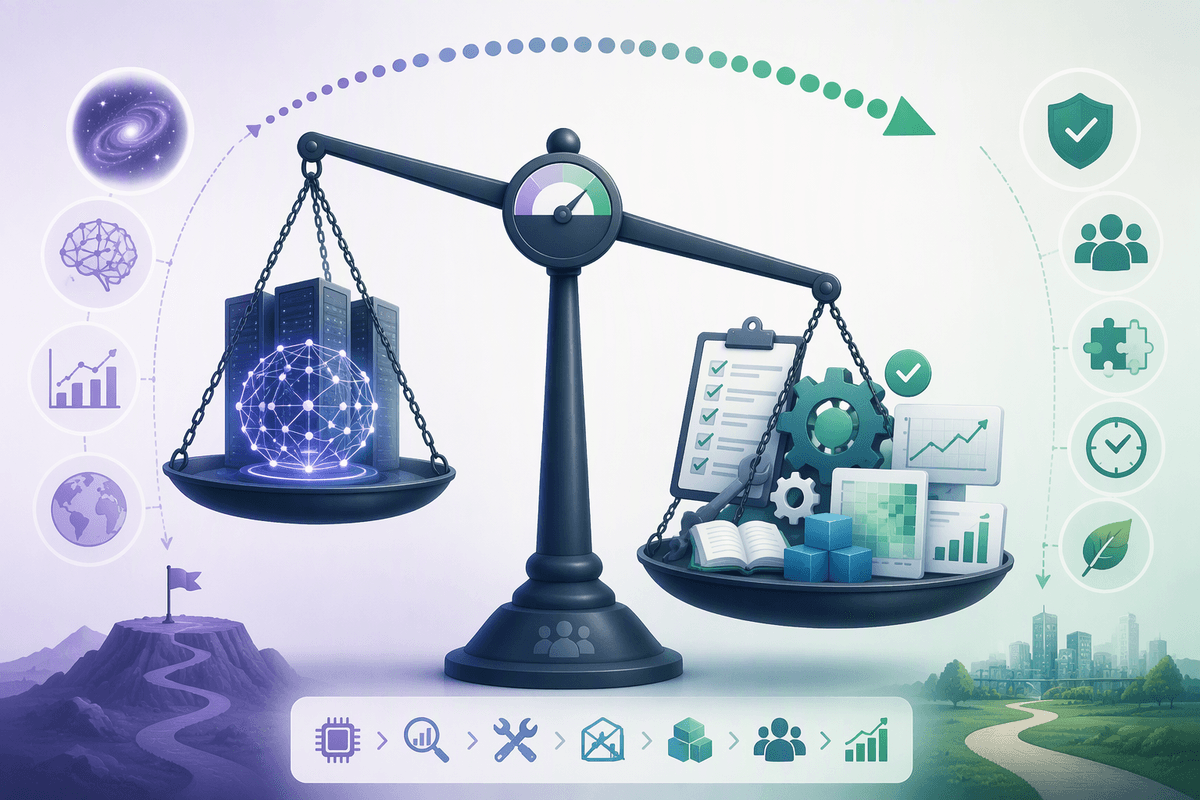
Research slowdowns rarely arrive as a clear stop signal. Their effects emerge gradually in the kinds of work that receive funding, approval, and recognition. When large training runs become harder to schedule or justify, research teams may favor projects with fewer obstacles, such as benchmark development, tooling, model distillation, and applied integrations. These efforts can improve evaluation practices and make existing systems more efficient. Yet they may also shift the definition of valuable research toward work that is easier to document and approve. Publication trends could follow suit, with more studies focused on evaluation and efficiency, fewer replications of frontier-scale experiments, and less methodological detail when researchers consider certain information sensitive.
These incentives can shape research careers well before they affect publication records. Early-career researchers who lack control over computing budgets may depend heavily on principal investigators, cluster administrators, or platform providers to approve their work. Hiring may also divide into positions with access to restricted research materials and roles limited to public models, potentially creating differences in pay, status, and career opportunities. International collaboration faces similar obstacles when projects require additional legal review or shared datasets and logs cannot cross borders freely. Administrative work adds to the burden through application forms, audits, and approval delays. For students and postdoctoral researchers working within fixed funding periods, those delays consume time that would otherwise go toward experiments, papers, and career development.
Safety upside vs. innovation downside: where tradeoffs bite
Even when a slowdown is framed as “just safety,” the benefit usually comes from making a few expensive steps unavoidable: pre-deployment evaluations, incident response planning, and time to investigate surprising behaviors before a model is copied widely. That can reduce the chance that a single rushed release becomes the default building block for thousands of downstream systems. It also improves accountability inside organizations, because someone has to sign their name to a process rather than a vibe.
The downside tends to show up where innovation depends on iteration speed and broad participation. Longer approval cycles make it harder to test risky-but-legitimate ideas, and compute gates can push frontier work into a smaller set of licensed actors with legal teams and dedicated compliance staff. Once that happens, the “safety tax” is not evenly shared: smaller labs and universities lose the ability to falsify claims through replication, while well-resourced groups keep moving—just with more paperwork. The tradeoff bites hardest when restrictions reduce independent scrutiny at the same time they reduce public capability growth.
If a slowdown happens, how researchers can adapt
Imagine you’re planning your next six months and the bottleneck isn’t ideas, it’s approvals and access. Adaptation starts with designing projects that degrade gracefully: studies that can run on smaller models, open weights, or controlled APIs without collapsing the research question. Put more weight on measurement work that stays valuable under constraint—evaluation design, adversarial testing, uncertainty reporting, and failure taxonomies—because these travel across model generations and are easier to justify to reviewers and compliance teams.
Operationally, treat compute and sensitive artifacts like shared infrastructure: write lightweight experiment plans, preregister key comparisons, and keep audit-ready logs so delays don’t erase momentum. Expect real costs: more coordination time, fewer “try it tonight” iterations, and higher reliance on partners who can sponsor access. The labs that can document rigor and share reproducible tooling will still shape the field, even when frontier runs are scarce.