Why Hallucinations Resist Simple Fixes
A model can pass a test set, answer common questions correctly, and still produce unsupported claims in production. Real users phrase requests in unexpected ways, provide incomplete context, and combine tasks that were never represented in evaluation data. Retrieval may return weak documents, prompts may create conflicting instructions, or a downstream system may distort the model’s output. The visible error is often just the final symptom.
That makes simple fixes unreliable. Tightening a prompt can reduce one failure pattern while creating another, and adding more retrieved content can increase confusion rather than accuracy. Sampling outputs manually also misses rare but costly errors and offers little evidence about where the failure began. Reliable improvement requires more than counting incorrect answers. Teams need visibility into the full request path, the signals surrounding each response, and the conditions that repeatedly precede a hallucination.
What Observability Reveals About AI Behavior
When a deployed assistant gives an incorrect answer, observability shows more than the text a user saw. It can connect the request to the prompt version, retrieved passages, tool calls, model response, latency, and user feedback. That record helps teams distinguish a knowledge gap from a retrieval failure, an instruction conflict, or a formatting step that changed the result. The distinction matters because each cause requires a different remedy.
Across many interactions, these signals reveal patterns that isolated reviews miss. Hallucinations may cluster around certain document types, query lengths, model versions, or low-confidence retrieval results. Evaluation scores can show whether groundedness or citation accuracy is declining, while prompt and retrieval monitoring exposes changes in the inputs that precede failures. Human feedback and targeted error analysis add context about severity and user impact. Observability does not prevent every unsupported answer, and collecting detailed traces adds storage, privacy, and processing costs. It does, however, turn vague concerns about reliability into evidence that engineers can investigate and act on.
Trace the Full Path to an Answer
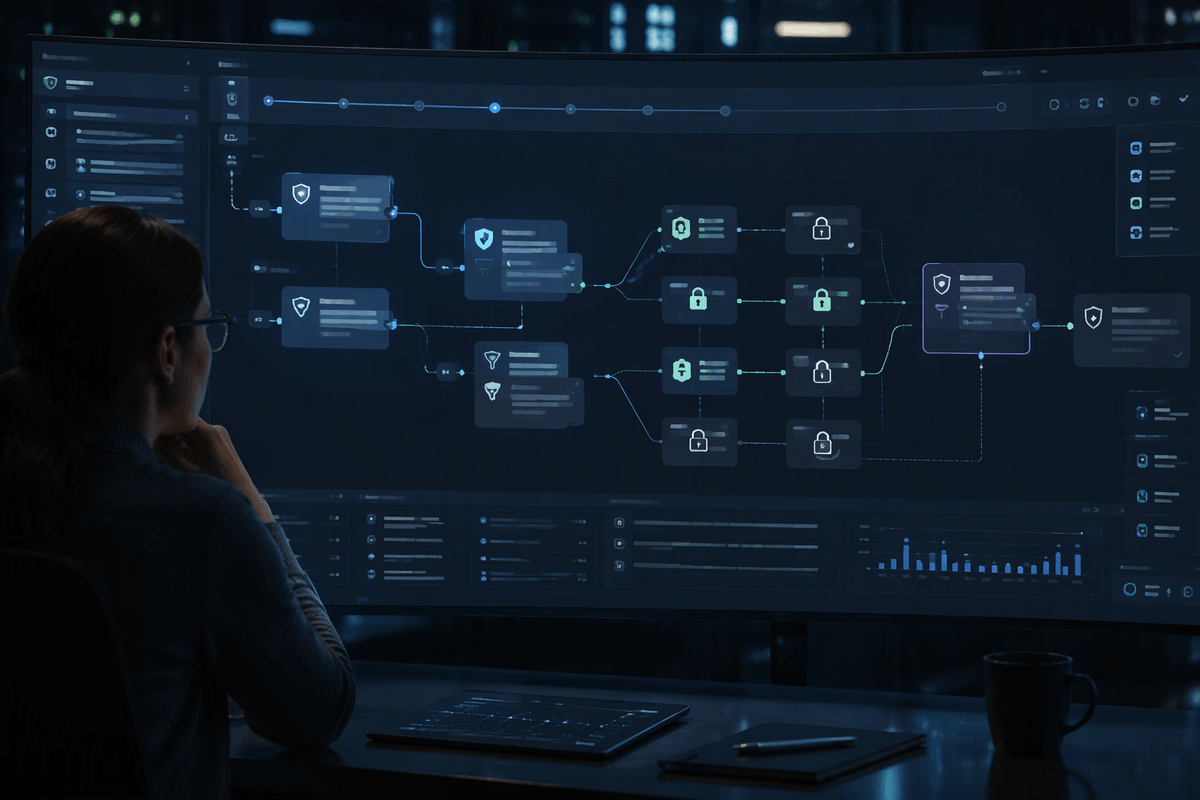
Start with a trace that follows one request from entry to final response. Record the user’s input, relevant session context, prompt and model versions, retrieval queries, documents returned, ranking scores, tool calls, intermediate transformations, and the answer delivered. A trace should preserve relationships between these events so an engineer can see whether the model lacked evidence, received the wrong evidence, or ignored evidence that was available. Without that chain, teams often focus on the wording of the final answer and miss an earlier failure.
For example, a support assistant may cite an outdated policy because the retriever selected an older document, not because the model invented the policy. Another response may become unsupported after a summarization step removes the qualifying language from a source. Comparing successful and failed traces makes these differences visible and helps isolate the smallest change worth testing. The practical challenge is deciding what to retain: full prompts and retrieved content improve diagnosis but can expose sensitive data and increase storage costs. Redaction, access controls, sampling, and consistent trace identifiers are therefore part of a usable observability design, not optional administrative details.
Measure Signals That Expose Hallucinations
A useful signal is rarely a single score. Track groundedness, citation accuracy, retrieval recall, answer refusal rates, and the share of responses that require correction. Break these measures down by model version, prompt template, document source, query type, and user workflow. A stable overall score can hide a serious regression in one important segment, such as account-specific questions or requests involving recently changed policies. Confidence scores and retrieval rankings can provide early warnings, but they should not be treated as proof that an answer is correct.
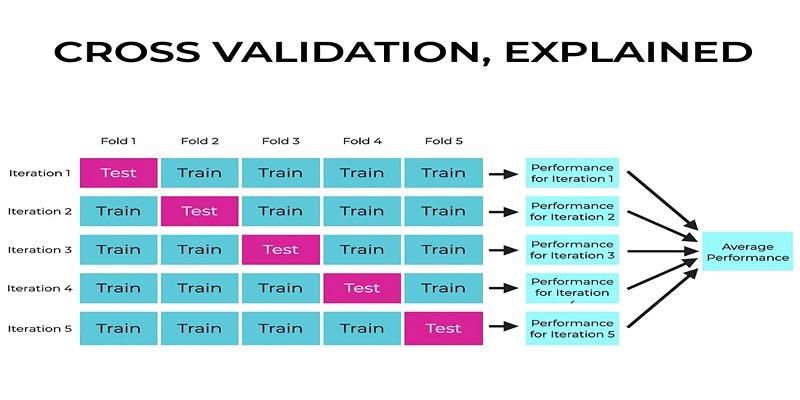
Pair automated metrics with feedback that explains what went wrong. Mark whether a response was unsupported, contradicted its sources, answered the wrong question, or omitted a necessary limitation. Review representative failures alongside successful traces, then compare the conditions they share. Error clusters often point to targeted actions: improve document freshness, adjust chunking, revise a prompt, change a routing rule, or add a refusal condition. Metrics also have limits. Human labels take time, evaluators can disagree, and optimizing one measure may weaken another. Keep a small, stable evaluation set for comparison while using production samples to discover failures the original tests never covered.
Connect Monitoring With Human Review
Automated monitoring can flag a suspicious response, but people are still needed to judge whether the failure matters and why it occurred. Route sampled traces and high-risk cases to reviewers with the surrounding evidence: the user request, retrieved sources, model output, confidence signals, and any prior corrections. A reviewer can then label the failure consistently, assess its impact, and note whether the system should have answered, asked for clarification, cited a source, or refused.
Those judgments become more useful when they feed back into monitoring rather than remaining in a ticket queue. Track reviewer labels by workflow, customer segment, model version, and failure type, then use recurring patterns to refine alerts and evaluation sets. Prioritize cases that could cause financial, legal, safety, or reputational harm, while sampling ordinary interactions to detect quieter regressions. Review programs have real limits: they consume expert time, labels may vary, and reviewers can become inconsistent at scale. Clear rubrics, calibration sessions, escalation paths, and periodic agreement checks help keep human feedback reliable enough to guide engineering decisions.
Turn Findings Into Safer Improvements
Once failure patterns are clear, change one part of the system at a time and measure the result against the same affected cases. If outdated sources drive unsupported answers, improve document ownership, freshness checks, or retrieval filters before changing the model. If the model drops important conditions during summarization, preserve source excerpts or adjust the prompt and output format. When failures come from ambiguous requests, asking a clarifying question may be safer than adding more instructions. Each intervention should have a hypothesis, an expected signal change, and a rollback plan.
Use traces and reviewer labels to build targeted evaluation cases from real failures, then test proposed changes against both the new cases and a stable regression set. Compare not only answer accuracy, but also refusal quality, citation behavior, latency, cost, and effects on unrelated workflows. A fix that reduces hallucinations by refusing too often may simply shift the problem to usability. Production rollout should therefore be gradual, with versioned prompts, retrieval configurations, and models, plus alerts for unexpected regressions. The goal is not to eliminate every error through increasingly complex controls. It is to make each improvement measurable, reversible, and focused on the conditions that actually produce harm.
Build Confidence Through Continuous Visibility
Confidence grows when visibility becomes part of normal operations rather than a response to an incident. Maintain dashboards that connect quality metrics with traces, reviewer feedback, prompt and retrieval changes, and deployment history. Set alerts for meaningful shifts, such as rising unsupported answers in a high-risk workflow or declining citation accuracy after a data update. Regularly review error clusters and refresh evaluation cases with newly observed failures so monitoring reflects how users actually interact with the system.
No dashboard guarantees reliable answers, and continuous collection brings ongoing privacy, storage, and review costs. The practical standard is whether the team can detect a problem early, explain its likely cause, and test a focused correction without losing sight of side effects. That feedback loop turns observability into operational confidence: not certainty that hallucinations are gone, but evidence that the system can be understood and improved.