Why machine-generated content is suddenly hard to spot
A year or two ago, a lot of AI content gave itself away with obvious tells: stiff phrasing, mismatched fingers, robotic cadence, or generic “stock photo” lighting. Those giveaways still happen, but they’re no longer dependable. The mainstream tools people actually use now produce cleaner grammar, steadier image details, and more natural-sounding voices, especially after a couple of quick edits by a human.
At the same time, the internet has trained all of us to consume fast and judge on vibes. A convincing screenshot, a clipped video, or a neatly formatted “leaked memo” can spread before anyone checks a source. That’s why detection has shifted from “spot the weirdness” to “prove where it came from,” which is where invisible signatures enter the conversation.
What “invisible signatures” mean in plain terms
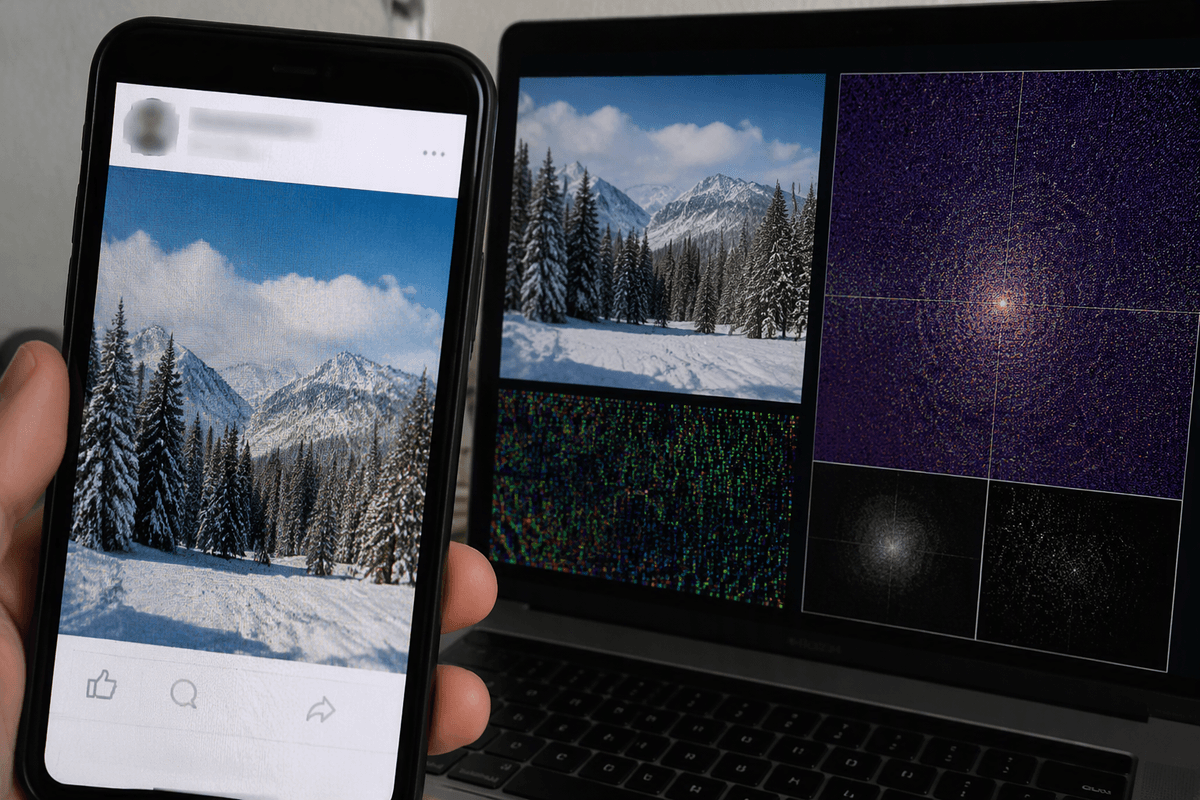
Picture a digital version of signing your name on the inside cover of a book. You can’t see it while you’re reading, but a reader with the right tool can confirm it’s there and, in some cases, who put it there. That’s the basic idea behind “invisible signatures”: small markers added on purpose to content so it can be checked later, even if nothing looks different to your eye or ear.
In practice, “signature” can mean two different things that often get mixed together. One is a watermark embedded into the content itself, like subtle patterns in pixels, word choices, or audio noise that a detector can measure. The other is provenance data—metadata or a tamper-evident record that travels alongside the file and says how it was made. Both help with attribution, but both come with costs: they require compatible tools on both ends, and they can be weakened or stripped by common sharing habits like screenshots, reposts, or re-exports.
How signatures get embedded across text, images, and audio
Think about the last time you copied text into a new document, ran it through a grammar tool, and then posted it. A text watermark has to survive that kind of handling, which is why many approaches live inside the generation process itself: the model is nudged to prefer certain word choices or punctuation patterns that, in bulk, form a detectable statistical “fingerprint.” It usually isn’t readable as a message, and it’s not unique per paragraph; it’s more like a measurable bias that a verifier tests for later.
For images, the embedding happens as tiny, spread-out changes to pixel values or frequency components—small enough not to be noticed, but structured enough that a detector can recover a signal after normal compression. Audio signatures use the same basic trick, hiding patterns in noise-like regions or frequencies people don’t focus on. Provenance works differently: a camera app or generator writes signed metadata and a tamper-evident history into the file, which is powerful until the content gets screen-recorded, re-encoded, or uploaded to platforms that strip metadata.
Where invisible signatures break: edits, laundering, and remix culture
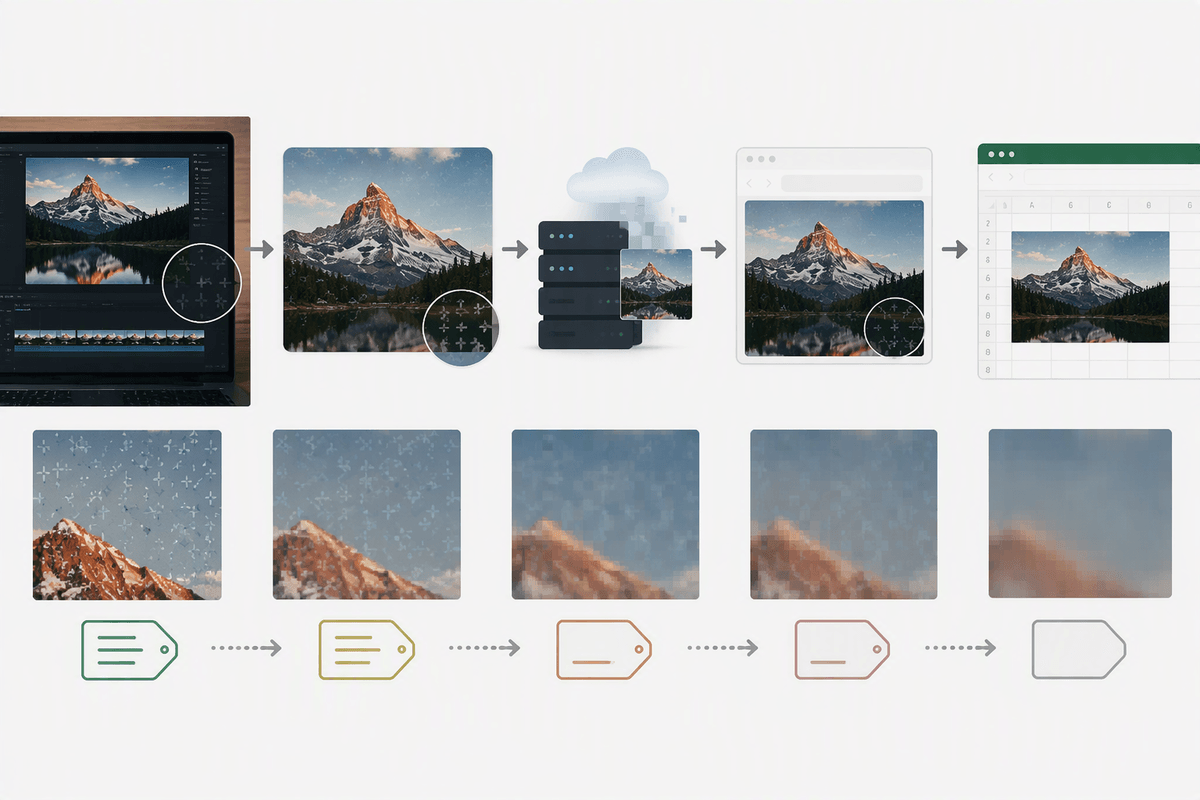
You can see the weak points by thinking about how people actually post content. A creator crops an image for a thumbnail, a platform re-encodes video, someone takes a screenshot to “save it before it gets deleted,” or a teacher copies a passage into a worksheet. Each step is an opportunity to blur or remove a watermark signal, and provenance data is even more fragile: screenshots, copy-paste, and screen recordings often drop the original metadata entirely.
More deliberate laundering is cheaper than most people expect. Text can be paraphrased sentence by sentence, translated and translated back, or lightly “humanized” by a different model so the original statistical fingerprint fades. Images can be resized, filtered, run through a denoiser, or re-generated by prompting an image model with the picture as reference. Audio can be re-recorded through speakers, mixed under music, or passed through noise reduction. None of this needs elite tools; it mostly costs time and a willingness to accept some quality loss.
Remix culture creates a final, messy edge case: when a meme, collage, or commentary clip blends sources, a signature might only prove that one ingredient in the mix had a marker, not which claims are synthetic.
Watermark vs provenance: choosing the right trust model
When you’re deciding what to trust, a watermark and a provenance record answer different questions. A watermark is like a stain inside the content: even if the file gets copied, re-uploaded, or stripped of metadata, a strong signal might still be detectable. That makes it useful for broad “was this likely generated?” screening at platform scale. The trade-off is that it’s usually probabilistic and model-specific. It can be weakened by routine edits, and it rarely tells you which tool made something or who was behind the keyboard.
Provenance is closer to a receipt. If it’s intact, it can say which device or app created the media, when, and what edits were applied, with cryptographic checks to show whether that history was tampered with. The provenance often fails in the way people actually share: screenshots, screen recordings, and re-exports can drop the trail. In practice, watermarks help when content is “loose,” while provenance helps when ecosystems agree to keep the chain unbroken—and that cooperation is the expensive part.
Adoption hurdles: incentives, standards, and who must cooperate
Consider what it would take for signatures to matter in a typical sharing chain: a generator has to add them by default, editing software has to preserve them, platforms have to detect and display them, and end users need a label they can understand without treating it as a verdict. Any missing link turns a “trust signal” into a niche feature. The incentives don’t naturally line up. Toolmakers may worry about performance costs, false positives, or giving competitors a roadmap to bypasses. Platforms may hesitate to add friction that slows uploads, creates support disputes, or implies they’re responsible for adjudicating authenticity.
Standards are the other bottleneck. If each model uses a private watermark and each camera app writes different provenance fields, verification becomes fragmented and expensive. Even with shared specs, someone has to run the public infrastructure: signing keys, revocation lists, and transparent rules for who is allowed to claim “verified.” The adoption has to be broad to be useful, but broad adoption requires governance that many actors don’t fully trust.
How to use signatures today without overtrusting them
In day-to-day use, treat signatures as a triage tool, not a lie detector. If a platform shows “no signature,” read that as “no usable trail survived,” not “human-made.” If it shows a watermark hit or a clean provenance chain, use it to decide what to verify next: find the earliest upload, check the account’s history, look for independent copies, and compare against primary sources. When stakes are high, ask for originals or camera-native files, because screenshots and re-exports erase the evidence you want.
Also plan for friction. Verification tools may be paywalled, labels can lag behind new models, and false positives or missing data will create real disputes for journalists, teachers, and moderators. The practical rule is to combine signals: signatures plus context (who posted, why now), plus content checks (does the claim match other reporting), plus basic media forensics. A signature can strengthen a case, but it shouldn’t be the only pillar holding it up.